TURNKEY INFRASTRUCTURE
We Do Not Simply Architect GPUs. We Architect the Entire AI Factory.
A production AI environment requires more than accelerators. Compute, networking, reusable context, orchestration, governance, and model routing must operate as one coordinated system.
Designed, integrated, and operational from network fabric to model routing.
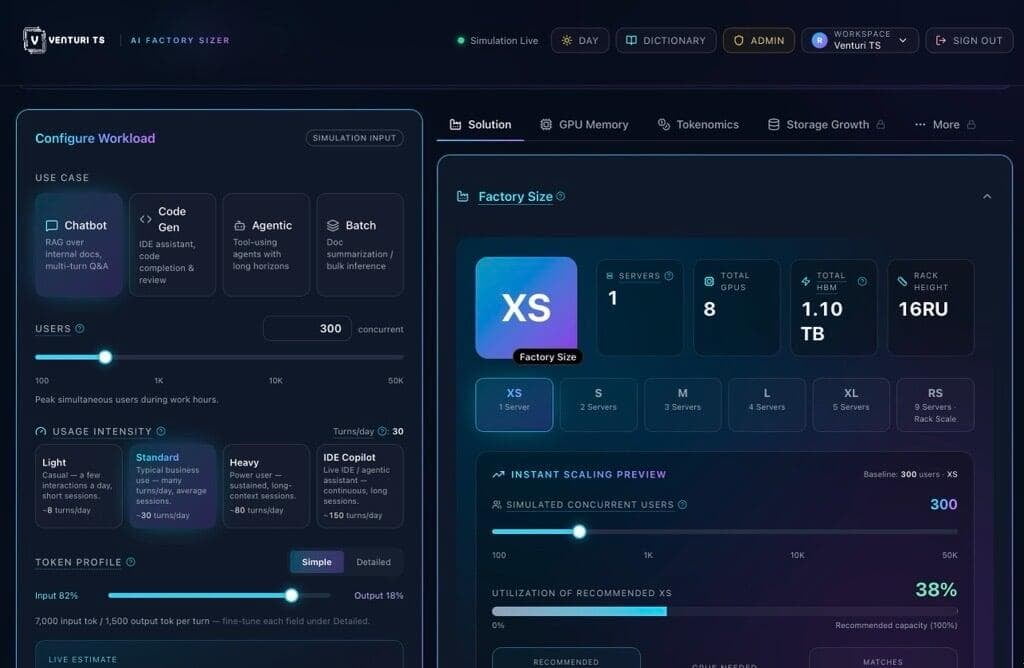
Right sized for your use-case.
INTELLIGENT PLACEMENT
Right Workload. Right
Model.
Right Location.
Venturi orchestrates AI from the enterprise core, evaluating each workload and routing execution to private models, cloud services, or frontier models according to cost, privacy, latency, and required capability.
COST • LATENCY • PRIVACY • DATA GRAVITY • POWER • CONTEXT • MODEL CAPABILITY
INFERENCE CONTEXT ARCHITECTURE
Give the
AI
Factory a Shared Memory.
Inference is where enterprise AI creates value. Venturi expands the context available to inference workloads across GPU memory, server memory, and a shared KV cache accessible throughout the AI factory.
More context. Less recomputation.
Better GPU economics.
PRODUCTIVE GPU CAPACITY
Stop
Asking
GPUs to Relearn What the
AI Factory Already Knows.
Repeated long-context inference can force GPUs to rebuild context they have already processed. Shared KV cache restores reusable context faster and returns GPU capacity to new inference work.
Restore what is known.
Compute what is new.
AI ECONOMICS
Reserve Frontier Intelligence for Frontier Problems.
Not every enterprise inference workload requires frontier-model economics. Purpose-matched private models can deliver the required outcome while reserving frontier services for tasks that justify their capability and cost.
Use the right intelligence at the right price.
PURPOSE-BUILT AI DENSITY
You Could Assemble Thousands of Small Systems.
Or Engineer One Complete AI Factory.
SIZED FOR USE-CASES, NOT GPUS
Stop Sizing GPUs. Start Sizing AI Outcomes.
Anyone can recommend a number of GPUs. Very few can tell you whether your AI application will perform with 500 users, a 128K context window, and your target response time. Our unique AI sizer models real customer workloads to predict performance and right-size infrastructure with confidence.
Built around users, models, context, and outcomes.